When you click on links to various merchants on this site and make a purchase, this can result in this site earning a commission. Affiliate programs and affiliations include, but are not limited to, the eBay Partner Network. As an Amazon Associate I earn from qualifying purchases. #ad #promotions


This model is punching WAY above what I expected a 27B could muster. Just from a params count standpoint it is such a dense dense! The performance side of 3.8 also pleasantly is highly tuned now for agentic running which is the best way to interact with your Local AI on complex asks. Speaking of complex asks, the arcade prompt failed from what I can tell zero tool calls in a two hour runtime! Now some turds would say “it’s not a zero shot if you are using an agent” which okay fine yes true but there needs to be a new category which is like, zero shot agentic. This model nailed that! There is also what I experienced nonstop with Deepseek V4 Flash and Qwen 3.6 27B which is many-shot agentic. Like you have to hold its hand and get it there and correct a lot of bad to even get something that works. There is a distinction and Qwen 3.8 27B destroyed on this. Straight up I am just blown away at that from a 27B and at 198K context utilized also and it kept consistent in its calling vision for inspection and playwright testing in a local LLM. More than half the time it was back and forth in a “I am fixing and inspecting with vision” loop EXACTLY LIKE I ASKED IT TO! Usually that starts out good, but falls apart 50-60K into the context in my experience with local llms. This is a level of reliability in tool calling throughout the entire context space that I think really opens up serious development possibilities.
DSP retro arcade https://arcade.digitalspaceport.com
Here is the arcadebox prompt now fully recovered!
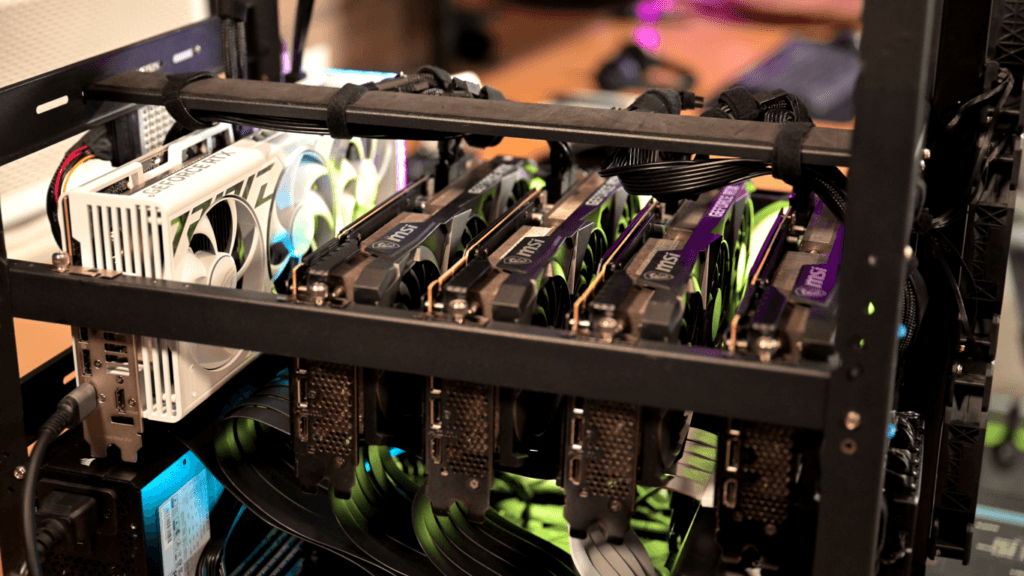
The Local Ai Rig
At 932 GB/s the GTX 3090 is a great GPU for local AI LLM running especially when it comes to dense models like Qwen 3.8 27B. Those models are harder for lower bandwidth AIO devices like a DGX Spark with it’s much lower 273 GB/s bandwidth which are better suited to mid to low active count MoE models. This is amplified by prompt processing demands in Agentic work.
While I have an extra 4090 in my rig, it was not used at all in running the model. Only the 4 3090s are used with vLLM (run block below) and while I have a NVlink on 2 of the 3090s it is doing much in running an LLM like this. The motherboard I have is an Asrock Creator 2.0 I already had but I would actually opt for a MC62-G40 if I was looking at this today. The CPU is actually a cheap Threadripper 3945wx which provides 128 lanes of PCIe Gen4 to the 5 dedicated slots I have that are electrically x16 Gen4 on this motherboard. This rig has dual PSUs and I am using 2 of the same line of PSUs, a Corsair HX1500i and HX1000i.
4x 3090 24GB https://geni.us/GPU3090
1x 4090 24GB https://geni.us/4090_24GB_GPU
WRX80 Asrock Creator 2.0 https://geni.us/ASRock_wrx80_creator
Gigabyte MC62-G40 https://geni.us/MC62-G40_MOBO
AMD Threadripper PRO 3945WX https://geni.us/AMD-TR-3945WX
256GB 2400 DDR4 DIMMs https://geni.us/256GB_DDR4_RAM
5x Gen4 x16 PCIe Risers https://geni.us/PCIe4_Riser_Cable
Rack Frame Chassis https://geni.us/GPU_Rack_Frame
PSU #1 https://geni.us/Corsair_HX1500i
PSU #2 https://geni.us/1000W_PSU
Dual PSU Adapter https://geni.us/dual-psu-adapter
H170i CAPELLIX 420mm https://geni.us/iCUE_H170i_Capellix
You can checkout the rig running in my Youtube Review Video as I go over this first run with it.
VLLM runblock
Artifacts from Arcade Session
You can find the complete folder and all files in the tar file here: arcade.tar
Here was the design document that it used to create this and update along the way as it progressed on the plan.