When you click on links to various merchants on this site and make a purchase, this can result in this site earning a commission. Affiliate programs and affiliations include, but are not limited to, the eBay Partner Network. As an Amazon Associate I earn from qualifying purchases. #ad #promotions
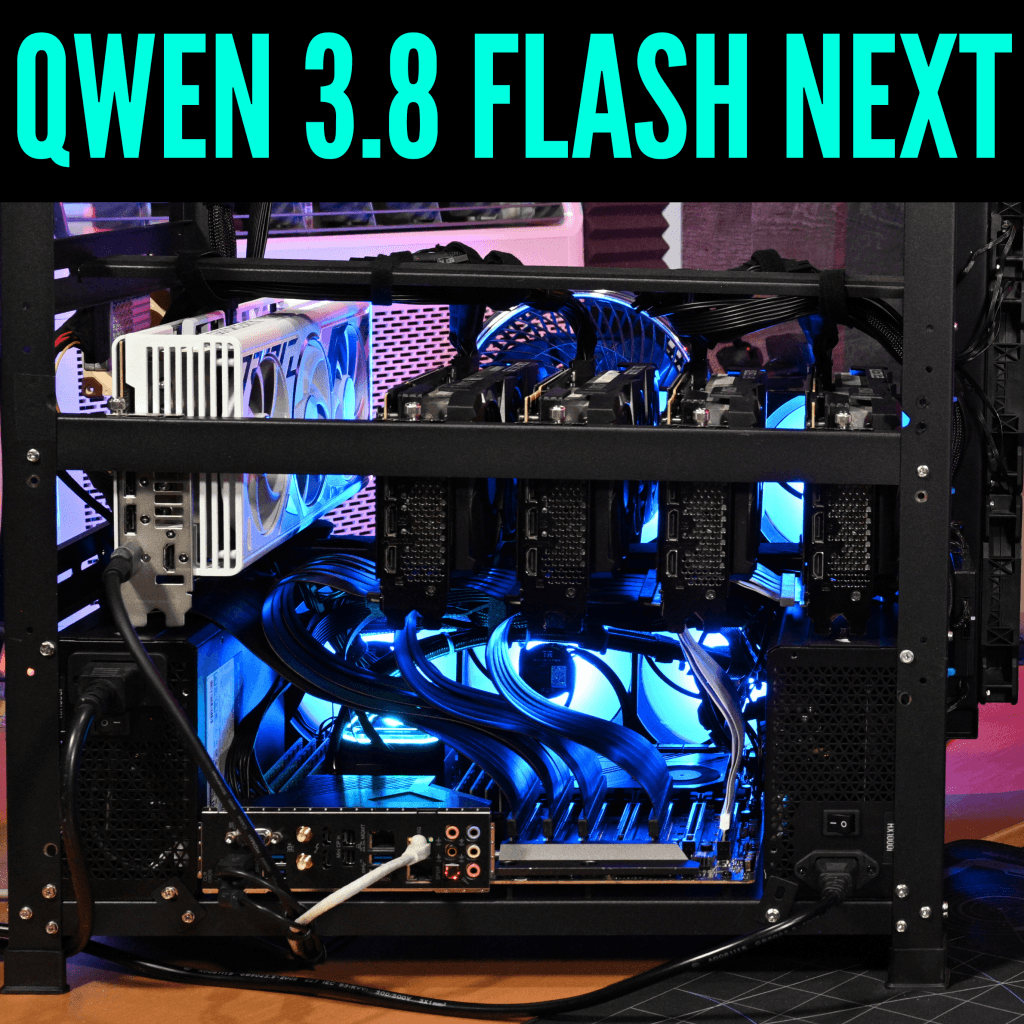


Qwen is like the gift that just keeps giving, and this time we are getting a new technology preview wrapped up Qwen 3.8 Flash Next which is capable of running surprisingly well in a Q4 thanks to the new N-GRAM offloading capability that sends this MoE’s performance up a step. Checkout the video if you have not yet we will be doing another now that I have this LLM ready for my hermes agent harness which will look at the quality of the model in deeper detail. It is running the runblock enhancer prompt now and I decided to test it out at 256K ctx to just see what that performance might look like and hopefully it can finish. Will update this article when I get some additional results on that also or good comments on the video with good tips and tricks!
Here is a decent starting point for a runblock that can fit in a 64GB RAM + Quad 24GB GPU VRAM/RAM footprint and stay with ya at least out to 128K context depth. Once you get this tuned up, drop your improvements to the videos comments section! Check below for some notes on things you want to check out and probably disable once there is llama.cpp main support in a day or so.
Qwen 3.8 Flash Next Llama.cpp runblock
Llama.cpp Optimization Trace
Qwen LOVES to overthink and if you watched the video you know how that ended up, sooo close. Here is a link to that big research trace you can feed to your bot.
Runblock Optimization Block
I have been using a variation of this script to get some pretty good insights into the various engine flags for a while and I think you might want to give this a try also. This has worked very well for a few recent models and does especially help when there is a day-0 launch that just has something new or different and you cant get it running right. Do update the docs links of course to be relevant to whatever LLM and engine it is your are trying to get your local ai rig running optimally. No need to hunt down recipes, your bot is pretty good at it for you!