NVIDIA GPU UNLOCK 3090 4090 2080ti

When you click on links to various merchants on this site and make a purchase, this can result in this site earning a commission. Affiliate programs and affiliations include, but are not limited to, the eBay Partner Network. As an Amazon Associate I earn from qualifying purchases. #ad #promotions
This may be the biggest improvement to local ai we have seen in at least the past 3 weeks from community contributors and this one really will speed up your long ranging agentic workflows especially! While it does NOT speed up your Decode TPS, it will dramatically speed up the performance you can hit with your prefill TPS. Of course we have a video on this which outlines the exact steps to get this up and running on Proxmox.

https://www.youtube.com/watch?v=opyJVz_T1GY

First off here are the repo’s for each of these GPU Unlockers by Generation

Turing Generation (2080ti etc) https://github.com/KohakuBlueleaf/KohakUnlock

Ampere Generation (3090 etc) https://github.com/Zagitta/gpu-unlock

Ada Generation (4090 etc) https://github.com/JustAResearcher/gpu-unlock-ada

Performance Improvement on my Quad 3090 Local Ai Rig

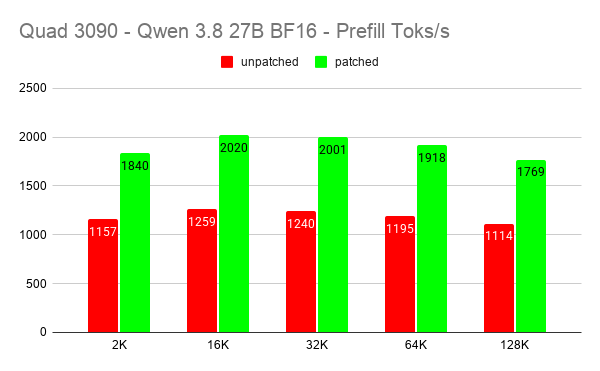
Here is what the Quad 3090 rig on Qwen 3.8 27B Full Precision performance improvement looks like with the Prefill Unlock Patcher for Ampere GPUS at C1!

2K 16K 32K 64K 128K
unpatched 1157 1259 1240 1195 1114
patched 1840 2020 2001 1918 1769

To put that in a bit more visual of terms, it is a very significant improvement in the prefill you can expect to hit for basically a few minutes of effort. Amazing unlock!

How to Test your prefill performance up to 128K

Create a file called prefill-bench.sh

Here is a quick C1 prefill test you can run before and after:

#!/usr/bin/env bash
# prefill-bench.sh — full prefill speed sweep: 2K 16K 32K 64K 128K
#
# Target (current endpoint): http://192.168.1.218:9876/v1
# Method: one request per depth, max_tokens=1, unique seeded prompt per
# depth (keeps the prefix cache cold), streaming.
#   TTFT            = request sent -> first streamed data line (= prefill)
#   prefill tok/s   = actual prompt_tokens (server usage) / TTFT
#
# Usage:
#   ./prefill-bench.sh                  # full sweep against the endpoint below
#   ./prefill-bench.sh 2048 16384       # only these depths
#   ./prefill-bench.sh http://host:port/v1 2048   # different endpoint
set -u

ENDPOINT="http://192.168.1.218:9876/v1"
API_KEY="nerdtastic"
DEFAULT_MODEL="qwen38-27b"
CURL_TIMEOUT=1800
SETTLE=3   # seconds between depths

# ---------------- args ----------------
ARGS=("$@")
DEPTHS=(2048 16384 32768 65536 131072)
if [ ${#ARGS[@]} -gt 0 ]; then
  if [[ ${ARGS[0]} == http* ]]; then
    ENDPOINT=${ARGS[0]}
    [ ${#ARGS[@]} -gt 1 ] && DEPTHS=("${ARGS[@]:1}")
  else
    DEPTHS=("${ARGS[@]}")
  fi
fi
# normalize 16k/16K -> 16384, validate numeric
for d in "${DEPTHS[@]}"; do
  if [[ $d == *[kK] ]]; then d=$(( ${d%[kK]} * 1024 )); fi
  if ! [[ $d =~ ^[0-9]+$ ]]; then
    echo "bad depth: $d (use e.g. 2048 or 16k)" >&2
    exit 1
  fi
done

# ---------------- helpers ----------------
label() { echo "$(( $1 / 1024 ))K"; }

# ~3.0 chars per token for this model's English
make_prompt() { # $1 = nominal token count
  local tokens=$1
  local chars=$(( tokens * 30 / 10 ))
  awk -v n="$chars" -v s="benchdepth${tokens}-pid$$-rand${RANDOM}${RANDOM}" 'BEGIN {
    base = "Seed " s ". The quick brown fox jumps over the lazy dog while the gray river runs slow under the old mill near the quiet town. ";
    out = "";
    while (length(out) < n) out = out base;
    printf "%s", substr(out, 1, n);
  }'
}

# ---------------- preflight ----------------
MODELS_JSON=$(curl -s -m 15 -H "Authorization: Bearer $API_KEY" "$ENDPOINT/models") || MODELS_JSON=""
MODEL=$(grep -o '"id":"[^"]*"' <<<"$MODELS_JSON" | head -1 | cut -d'"' -f4)
[ -z "$MODEL" ] && MODEL="$DEFAULT_MODEL"

echo "PREFILL BENCH"
echo "endpoint : $ENDPOINT"
echo "model    : $MODEL"
echo "time     : $(date -u '+%Y-%m-%d %H:%M UTC')"
echo ""
printf ' target    actual   prefill (s)   prefill (tok/s)\n'
printf ' ------   ------   -----------   ---------------\n'

RESULTS=()

for d in "${DEPTHS[@]}"; do
  text=$(make_prompt "$d")
  bodyfile=$(mktemp)
  trap 'rm -f "$bodyfile"' EXIT
  printf '{"model":"%s","messages":[{"role":"user","content":"%s"}],"max_tokens":1,"temperature":0,"stream":true,"stream_options":{"include_usage":true}}' "$MODEL" "$text" > "$bodyfile"

  ttft="" ptt="" first=0
  start=$(date +%s.%N)
  while IFS= read -r line; do
    if [ "$first" -eq 0 ] && [[ $line == data:* ]]; then
      now=$(date +%s.%N)
      ttft=$(awk -v a="$start" -v b="$now" 'BEGIN{printf "%.3f", b-a}')
      first=1
    fi
    if [[ $line == data:* && $line == *usage* ]]; then
      ptt=$(grep -o '"prompt_tokens":[0-9]*' <<<"$line" | head -1 | cut -d: -f2)
    fi
  done < <(curl -sN --no-buffer -m "$CURL_TIMEOUT" \
      -H "Authorization: Bearer $API_KEY" \
      -H 'Content-Type: application/json' \
      --data-binary @"$bodyfile" "$ENDPOINT/chat/completions")

  if [ "$first" -eq 0 ] || [ -z "$ttft" ]; then
    actual="-" rps="ERR"
    printf ' %6s   %6s   %11s   %13s\n' "$(label "$d")" "$actual" "-" "no response"
    RESULTS+=("$(label "$d")|-|-|ERR")
  else
    # fall back to estimate if the server did not report usage
    if [ -z "$ptt" ]; then
      ptt=$(( ${#text} * 10 / 30 ))
      ptt="${ptt}~"
    fi
    rps=$(awk -v t="$ttft" -v p="${ptt%~}" 'BEGIN{printf "%.0f", (t>0)? p/t : 0}')
    printf ' %6s   %6s   %11s   %13s\n' "$(label "$d")" "$ptt" "$ttft" "$rps"
    RESULTS+=("$(label "$d")|$ptt|$ttft|$rps")
  fi
  [ "$d" != "${DEPTHS[${#DEPTHS[@]}-1]}" ] && sleep "$SETTLE"
done

echo ""
echo "done: ${#DEPTHS[@]} depths, $(date -u '+%Y-%m-%d %H:%M UTC')"