Local Ai GPU Maintenance, Repadding and Repasting Guide
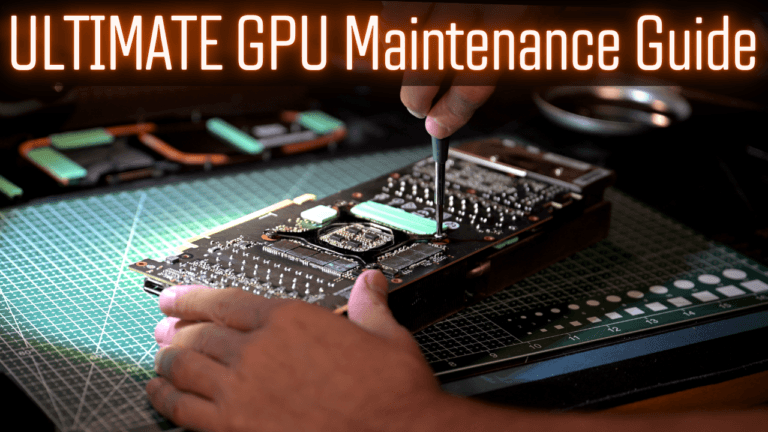
It is WAY too expensive to have a GPU fail out so here is some helpful tips and tricks that can keep your cards running in tip top shape and a few things to look
It is WAY too expensive to have a GPU fail out so here is some helpful tips and tricks that can keep your cards running in tip top shape and a few things to look
Okay this is a fast and good model and a real community lift to get as stupid simple of a playbook for you as I could that solves THE NUMBER ONE critical request for Qwen
Qwen is like the gift that just keeps giving, and this time we are getting a new technology preview wrapped up Qwen 3.8 Flash Next which is capable of running surprisingly well in a Q4
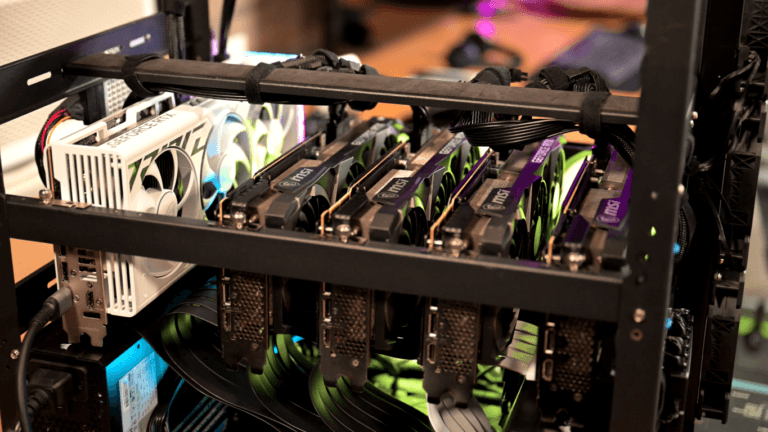
This model is punching WAY above what I expected a 27B could muster. Just from a params count standpoint it is such a dense dense! The performance side of 3.8 also pleasantly is highly tuned

I had an unused older optiplex mid tower (MT) sitting in a corner doing nothing and I though maybe I can turn that into some sort of local ai rig on the cheap. I had
The basic way to get some simple benchmarks done with vLLM on your Local Ai server follow here. This guide assumes you already have followed THE PRIOR GUIDES to get up to this point. You
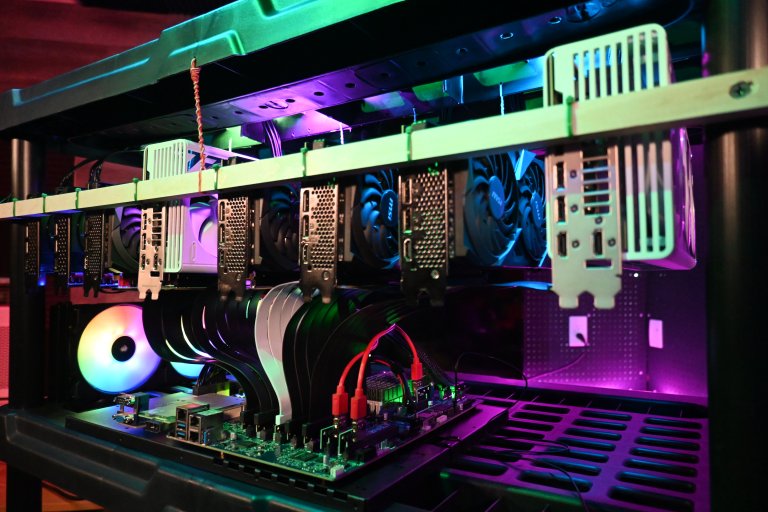
Local Ai 8 GPU Home Server Build Guide Creating a large count GPU local Ai server is a challenging proposition given the current state of elevated GPU prices we have as a result of several

The Dell R730xd is still an amazing piece of kit for homelabbers, local media storage hoarders and a perfect for budget high performance 10 or 25 GbE network shares to storage. While some may lament

Qwen3 is an exciting new Multimodal Audio, Video, Text and Image LLM that is able to be ran fully locally on a modest ai rig. Here are the cmds to get you up and running.

*For unknown reasons, MS pulled their github repo and weights for the large off HF as I found out 9/4/2025. I updated the links below to reflect this. They gave no reason why which is